Agent Memory Is Not a Database: Start with an Event Log
I break agent memory into writing, storage, retrieval, assembly, and forgetting, then outline a minimal implementation path that starts with a durable event log.

I am still trying to decide what “memory” should mean in an agent. I did not begin with a database. I began by comparing how different tools use the word.
OpenAI Agents SDK calls a single conversation’s history session memory; LangGraph separates thread-scoped short-term state from long-term data that spans threads. In the material I am comparing, the same word can refer to a complete conversation, a checkpoint, user preferences, a search index, or even a set of reusable Skills.
That boundary is still blurry for me. I keep seeing the temptation to point a vector database at several different problems and expect “memory” to appear on its own. I do not know yet which parts need separate systems.
This article records an experiment that is still in progress. It is not a product benchmark or a blueprint for every production agent. My current working hypothesis is:
I am treating agent memory as a data lifecycle. I want to preserve traceable events first, then use real failures to decide whether summaries, facts, search, or graphs are worth adding.
I am testing when memory becomes context
I am using these as provisional definitions:
| Name | What it is responsible for | What it is not |
|---|---|---|
| Context | The instructions, messages, tool results, and retrieved data the model actually sees for one inference | All history stored in the backend |
| Session state | Messages, plans, checkpoints, and pending state for one thread or task | User memory shared across sessions |
| Agent memory | Data governed by policies for writing, storing, retrieving, assembling, and forgetting, for future use | A particular database product |
| External knowledge base | Domain knowledge such as documents, policies, code, or product data | Personal records produced through user-agent interactions |
Under these definitions, memory and context sit at different layers. Data can remain in the backend for a long time, but it becomes context only when the system selects it, checks authorization, and places it in the current input. Clearing context does not mean the backend data has been deleted.
I am also keeping content types and retrieval methods separate for now. Episodic memory records what happened and when. Semantic memory stores relatively stable facts. Vector search is only one way to find data. An episodic event can live in an event table, full-text index, and vector index at the same time. I am treating these as compatible choices, but I have not tested which combination will be useful.
The five responsibilities I am using as a test map
Once I separate those terms, I can draw the data flow I want to test. Each step asks a different question. Corrections and deletions also need a path back to storage:
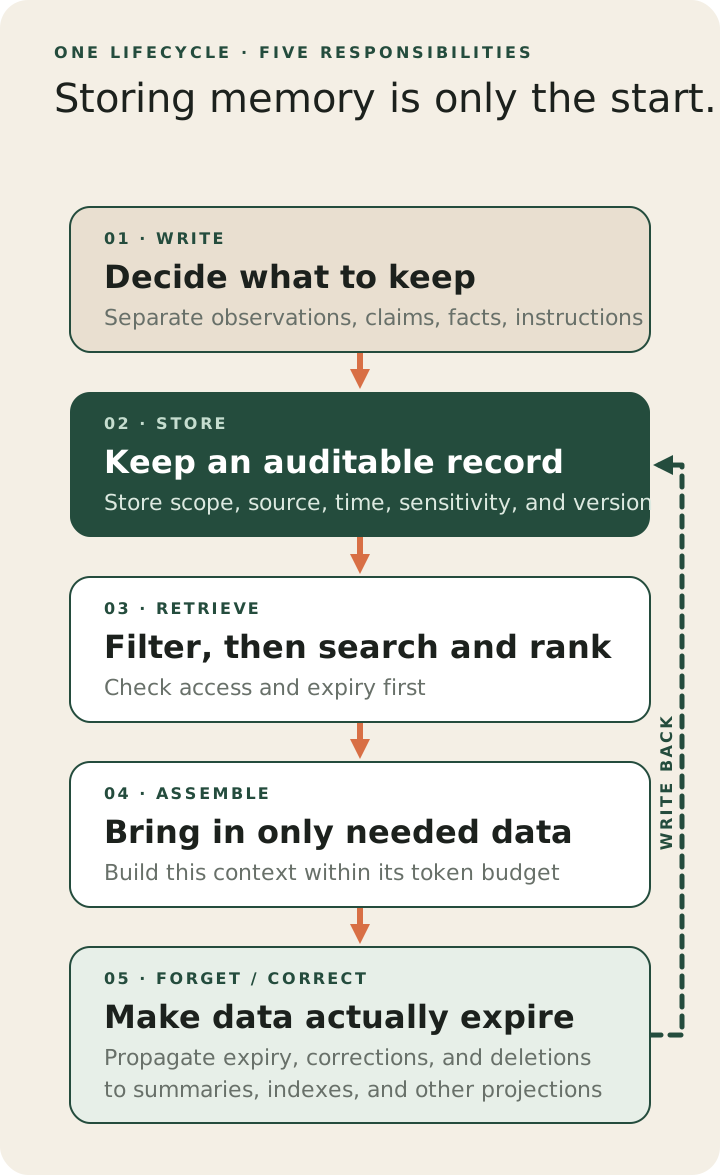 This is the map I am testing. I am still checking whether these boundaries are useful in practice.
The first implementation I am testing: bounded context and a durable event log
For a new agent, the first version I am trying has two pieces: a bounded current context and a durable event log.
In this version, the event log stores user messages, model outputs sent externally, tool calls and results, approvals, errors, and references to artifacts. I am not storing the model’s hidden reasoning. Each run gets only the current request, task state, recent events, and data explicitly needed for that request.
request
   |
   +-- append event ----------------------+
   |                                      |
   +-- read task state                    | durable event store
   +-- read recent events within budget   |
   +-- assemble context -> model -> tools-+
                                          |
                                          +-- optional projections later
                                              summary / facts / search / graph
At the moment, I am treating raw events as the canonical record. Summaries, profiles, full-text indexes, embeddings, and graphs are rebuildable projections. The reason for this choice is traceability: an incorrect summary can be rebuilt, and the search method can change without making the first derived form the only truth. I still need to test whether the extra storage and write-back work is worth it.
This choice has limits. It assumes a conventional database can still handle the raw event volume and that the product values auditability, correction, and deletion. For a one-off task with no cross-turn value, I may not need long-term memory at all.
I am adding a layer only when a failure gives me a reason
I do not know yet whether a profile, vector index, or knowledge graph will be useful in the first version. For now, I am using an observed problem as the reason to try a layer:
| Candidate layer | When it is worth adding | Constraint to keep |
|---|---|---|
| Summaries | Long threads exceed token or latency budgets, and truncation begins to hurt task success | Link every summary to event IDs; never replace the raw record |
| Structured facts / profile | The same stable facts are asked for repeatedly, event scanning is unreliable, and a small schema covers most cases | Keep sources, validity periods, and superseded versions; do not let model inference silently overwrite facts |
| Full-text search | Names, codes, error messages, and exact wording must be found reliably | Synonym paraphrases may not have enough recall |
| Vector / hybrid search | Volume or natural-language paraphrases mean key lookup and full-text search miss recall or latency targets | Similarity is not relevance; exact IDs still deserve structured queries |
| Knowledge graph | Real queries repeatedly need multi-hop relationships or corpus-wide aggregation, and evaluation shows the gains offset update costs | Entity resolution, stale relationships, and extraction errors all need governance |
Provider-managed conversation state is another option I am comparing. It can reduce the plumbing around sessions and compaction, but it cannot decide fact conflicts, cross-tenant permissions, or deletion of projections for an application. For cases where I need auditability, portability across models, or explicit data governance, I am keeping the canonical event log in the application.
The questions I am using for now
Before I add a memory layer, I start with the use case. What is actually failing because the agent “forgets”? I then check whether the canonical source is chat, a tool system, documents, or model inference, and whether the scope is a thread, user, agent, or tenant. I need to know who can read and write that data, how corrections, expiry, and deletion propagate to every projection, and which temporal-holdout metric must pass before the extra latency and maintenance cost is worthwhile.
These questions will not give an agent “infinite memory,” and I do not expect them to settle the design by themselves. They give me a way to record the source, purpose, and lifespan of each piece of data while I test whether another layer is justified.
For now, my working setup is bounded context and a durable event log. Summaries, facts, vector search, and graphs can come later if the tests show that I need them. I do not know yet whether this is the best option. I am still working through the alternatives by trial and error, checking which ones hold up when the agent fails.